A formula is only helpful when you know which question it answers. Are you finding the chance of an event, describing data you collected, or estimating something about a larger group? That choice matters more than memorizing symbols. I find probability and statistics formulas explained most clearly when I use one example across all three tasks.
Imagine a US community center surveying residents about a new evening class. We will use its responses to calculate chances, describe attendance, and see what a sample can tell us. Every equation below uses plain text, so you can copy and paste it into Google Docs.
Start With the Symbols
A population is the entire group you want to understand. A sample is the smaller group you measure. If the center wants to know what all local residents think but surveys 100 of them, those 100 people form the sample.
| Symbol | Meaning | Quick reminder |
| P(A) | Probability of event A | A value from 0 to 1 |
| n | Number of observations in a sample | Count the measured values |
| N | Number of observations in a population | Count every value in that population |
| x̄ | Sample mean | Average of the sample |
| μ | Population mean | Average of the population |
| s | Sample standard deviation | Spread measured from a sample |
| σ | Population standard deviation | Spread measured from a population |
The distinction between sample and population controls several formulas. In particular, sample variance divides by n − 1, while population variance divides by N.
Probability Formulas: Counting, “Or,” and “And”
Basic Probability and Complements
If every outcome is equally likely, divide favorable outcomes by all possible outcomes:
P(A) = number of favorable outcomes / number of possible outcomes
For a fair six-sided die, P(rolling a 4) = 1 / 6. Do not use this counting shortcut when outcomes have unequal chances. Survey responses, for example, need their observed proportions or a suitable probability model.
A complement means “A does not happen”:
P(not A) = 1 − P(A)
Suppose 60 of 100 surveyed residents say they would attend. Their observed proportion is 60 / 100 = 0.60. The proportion who would not attend is 1 − 0.60 = 0.40. This describes the surveyed group; it is not automatically the exact probability for every resident.
Addition, Multiplication, and Conditional Probability
Use the addition rule for “A or B”:
P(A or B) = P(A) + P(B) − P(A and B)
The subtraction removes people counted in both groups. If 60% favor an evening class, 30% favor a weekend class, and 20% favor both, the chance that a randomly selected survey respondent favors at least one is 0.60 + 0.30 − 0.20 = 0.70.
For “A and B,” use the multiplication rule:
P(A and B) = P(A) × P(B given A)
Conditional probability changes the group you are considering:
P(B given A) = P(A and B) / P(A)
Using the survey figures, P(weekend given evening) = 0.20 / 0.60 ≈ 0.333. About one-third of respondents who favor evenings also favor weekends. You can multiply P(A) × P(B) only when A and B are independent. OpenStax explains both rules and their conditions.
Bayes’ Theorem
Bayes’ theorem reverses a conditional probability when you have new information:
P(A given B) = [P(B given A) × P(A)] / P(B)
Suppose 40% of survey respondents are parents. Among parents, 75% favor the evening class; among nonparents, 50% favor it. First, find the overall proportion favoring evenings:
P(evening) = (0.75 × 0.40) + (0.50 × 0.60) = 0.60
Now ask: If a respondent favors evenings, what is the chance they are a parent?
P(parent given evening) = (0.75 × 0.40) / 0.60 = 0.50
That 50% differs from the 75% of parents who favor evenings. The order after “given” changes the question. Penn State’s probability course covers this reversal.
Descriptive Statistics Formulas: Center and Spread
Mean, Variance, and Standard Deviation
Suppose five pilot classes draw 8, 10, 10, 12, and 15 attendees. Their sample mean is:
x̄ = sum of all sample values / n = 55 / 5 = 11
The mean tells me typical attendance, but it hides variation. Sample variance measures squared deviations from the mean:
s² = sum of (each value − x̄)² / (n − 1)
Here, the squared deviations are 9, 1, 1, 1, and 16. Their sum is 28, so s² = 28 / 4 = 7. Sample standard deviation returns the result to the original units:
s = √s² = √7 ≈ 2.65 attendees
If those five classes were every class in the population I cared about, I would instead use:
μ = sum of all population values / N
σ² = sum of (each value − μ)² / N
σ = √σ²
Notice the practical distinction: standard deviation describes variation among individual class counts. It does not measure how precisely we have estimated the population mean.
Z-Scores and the Normal Distribution
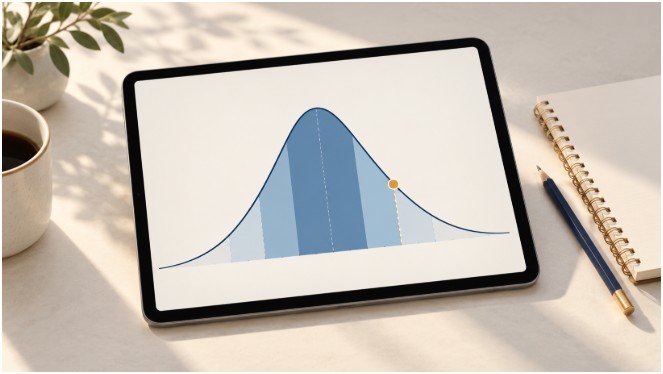
A z-score expresses a value’s distance from a population mean in standard deviation units:
z = (x − μ) / σ
If attendance across a well-defined population of classes has μ = 11 and σ = 2, attendance of 15 gives z = (15 − 11) / 2 = 2. That class is two standard deviations above the mean.
For data that follow an approximately normal, bell-shaped distribution, the empirical rule places about 68% of values within one standard deviation of the mean, 95% within two, and 99.7% within three. I would not apply those percentages blindly to strongly skewed attendance data or treat five classes as proof of a normal shape.
Inferential Statistics: From a Sample to an Estimate
Standard Error, Confidence Intervals, and the t-Statistic
Standard error describes how much a sample mean would vary across repeated random samples. When the population standard deviation is unknown, estimate it with:
SE = s / √n
For the five classes, SE = 2.65 / √5 ≈ 1.18 attendees. A larger sample generally reduces standard error, though it cannot repair a biased way of choosing classes.
A confidence interval adds a margin of error around a sample mean. For a suitable sample when the population standard deviation is unknown, use a t critical value:
confidence interval = x̄ ± t* × (s / √n)
For the five-class example, the 95% t critical value with n − 1 = 4 degrees of freedom is about 2.776. The calculation gives 11 ± (2.776 × 1.18), or approximately 7.71 to 14.29 attendees. This interval relies on assumptions that a tiny sample makes difficult to check, so I would treat it as a calculation example, not a firm planning forecast.
A 95% confidence level describes the long-run success rate of the interval-building method across repeated samples. It does not mean this particular fixed interval has a 95% chance of containing the fixed population mean. To compare a sample mean with a proposed value μ₀, use:
t = (x̄ − μ₀) / (s / √n)
The t value alone does not settle a hypothesis test; you also need the test direction, degrees of freedom, and assumptions. NIST explains confidence intervals for a mean and the effect of sample uncertainty.
Formula Reference Table
| If your question is… | Copy-ready formula | Check before using it |
| What is the chance of A? | P(A) = favorable outcomes / possible outcomes | Outcomes must be equally likely. |
| What is the chance A does not occur? | P(not A) = 1 − P(A) | Define A clearly. |
| What is the chance of A or B? | P(A or B) = P(A) + P(B) − P(A and B) | Subtract the overlap. |
| What is the chance of A and B? | P(A and B) = P(A) × P(B given A) | Use P(B) instead only if independent. |
| What is the sample average? | x̄ = sum of sample values / n | Check for values that distort the mean. |
| How spread out is the sample? | s = √[sum of (each value − x̄)² / (n − 1)] | Use n − 1 for sample standard deviation. |
| How precise is the sample mean? | SE = s / √n | Consider sampling quality and assumptions. |
| What range estimates the mean? | x̄ ± t* × (s / √n) | Choose the critical value and method correctly. |
Frequently Asked Questions
1. What is the difference between probability and statistics formulas?
Probability calculates chances from a model; statistics summarizes observed data and uses samples to estimate population values.
2. When do I use n − 1 instead of n?
Use n − 1 for sample variance or sample standard deviation when estimating population spread.
3. Is standard error the same as standard deviation?
No. Standard deviation describes individual values; standard error describes the sampling variation of a statistic such as the mean.
4. When should I use a z-score instead of a t-statistic?
Use a z-score to locate a value relative to a known population mean and standard deviation; a t-statistic commonly tests a mean when population spread is unknown.
Your Calculator Can Wait; Choose the Formula First
When I face a new problem, I write its question in ordinary words: chance, average, spread, or estimate? Then I identify whether I have a population, a sample, or conditional information.
That two-step habit makes probability and statistics formulas explained far more useful than a memorized sheet. Try it on one small dataset of your own, and check what each answer actually claims.
Leave a Reply